2026 开源大模型消费级显卡显存报告:64 个开源模型在 8–80 GB 显卡和 Mac 上
本报告的每个数字都在构建时由站内 64 个开源模型的数据和显存计算器的同一套函数算出,没有手填数字。设定:Q4_K_M 权重(gpt-oss 按发布的 MXFP4),32K 上下文,单个请求,FP16 KV 缓存,显存至少剩 0.5 GB 才算放得下。数据版本 1.2026-09-30,模型数据核对于 。GB = GiB。
可引用的结论
- 在 32K 上下文下,63 个开源模型单个请求的 FP16 KV 缓存从 0.19 GB(Nemotron 3 Nano 30B-A3B)到 11.0 GB(Mistral Medium 3.5 128B)不等,相差 58.7 倍。
- 参数量决定不了 KV 缓存:Nemotron 3 Nano 30B-A3B(31.6B 参数)在 32K 下只需 0.19 GB KV 缓存,而 Granite 4.2 30B(29.3B)需要 8.0 GB,是前者的 43 倍。
- 64 个开源模型中有 34 个能以 Q4_K_M、32K 上下文放进 24 GB 显卡,其中最大的是 Ornith 1.5 35B-A3B,需要 23.5 GB。
- 在 Q4_K_M、32K 上下文下,48 GB 显卡能放下的最大模型并不比 32 GB 更大:两者都是 K2-Horizon MoVA 36B-A4B,多出的显存只换来更长的上下文(37K 到 115K token);Llama 3.1 70B 需要 55.2 GB。
- 128 GB 内存的 Mac(GPU 可用 96 GB)能以 Q4_K_M、32K 上下文运行 64 个模型中的 44 个,最大到 Mistral Medium 3.5 128B(127.7B,91.8 GB)。
如何引用
纯文本:数据来源:ModelVRAM(modelvram.com),《2026 开源大模型消费级显卡显存报告》,https://modelvram.com/reports/local-llm-vram-2026/,数据版本 1.2026-09-30(2026-09-30),CC BY 4.0。
APA: ModelVRAM. (2026). 2026 Local LLM VRAM Report (Version 1.2026-09-30) [Data set]. https://modelvram.com/reports/local-llm-vram-2026/
数据以 CC BY 4.0 许可发布:可以复制、改编和商用,只需署名“Data: ModelVRAM”并链接到本页。
各档显存能放下的最大模型(Q4_K_M,32K)
按总参数排序取最大的一个;“最长上下文”是该模型在这档显存上还剩 0.5 GB 时能开到的上下文。Mac 按 macOS 允许 GPU 使用的统一内存计算。
| 显存 | 放得下的模型数 | 最大的模型 | 设定 | 显存(32K) | 最长上下文 |
|---|---|---|---|---|---|
| 8 GB 显卡 | 11 / 64 | LensVLM 9B | Q4_K_M | 7.43 GB | 33K |
| 12 GB 显卡 | 18 / 64 | Gemma 4 12B | Q4_K_M | 8.98 GB | 178K |
| 16 GB 显卡 | 19 / 64 | gpt-oss-20b | MXFP4 | 15.44 GB | 34K |
| 24 GB 显卡 | 34 / 64 | Ornith 1.5 35B-A3B (MoE) | Q4_K_M | 23.47 GB | 33K |
| 32 GB 显卡 | 37 / 64 | K2-Horizon MoVA 36B-A4B (MoE) | Q4_K_M | 30.31 GB | 37K |
| 48 GB 显卡 | 37 / 64 | K2-Horizon MoVA 36B-A4B (MoE)与更小一档相同 | Q4_K_M | 30.31 GB | 115K |
| 80 GB 显卡 | 43 / 64 | Qwen3.5 122B-A10B (MoE) | Q4_K_M | 78.85 GB | 57K |
| 64 GB Mac(可用 48 GB) | 37 / 64 | K2-Horizon MoVA 36B-A4B (MoE)与更小一档相同 | Q4_K_M | 30.31 GB | 115K |
| 128 GB Mac(可用 96 GB) | 44 / 64 | Mistral Medium 3.5 128B | Q4_K_M | 91.75 GB | 41K |
48 GB 这一档的空缺
48 GB 显卡(和 64 GB Mac)能放下的最大模型与 32 GB 相同,都是 K2-Horizon MoVA 36B-A4B (MoE),多出的显存只让上下文从 37K 增加到 115K。 原因是数据集里 40B–75B 参数的模型只有 1 个(Llama 3.1 70B 在 Q4_K_M、32K 下需要 55.2 GB),都放不进 48 GB。 这是本数据集的覆盖空缺,不代表 48 GB 显卡跑不了这个尺寸的其他模型;我们没有为这一档补编数据。
32K 上下文下的 KV 缓存:从小到大
单个请求、FP16。最小的 Nemotron 3 Nano 30B-A3B (MoE) 为 0.19 GB,最大的 Mistral Medium 3.5 128B 为 11.0 GB,相差 58.7 倍。差距来自注意力结构:只有部分层保存完整 KV 的混合模型,缓存远小于每层都是全注意力的模型。
| # | 模型 | 参数 | KV 缓存(32K) | 结构(英文) |
|---|---|---|---|---|
| 1 | Nemotron 3 Nano 30B-A3B (MoE) | 31.6B3.5B 激活 | 0.19 GB | 6 of its 52 layers use full attention and 46 are Mamba or feed-forward layers with no growing cache |
| 2 | Ling 3.0 Tiny 7.9B-A1.3B (MoE) | 7.9B1.3B 激活 | 0.21 GB | 6 of its 24 layers use multi-head latent attention and 18 are KDA recurrent layers with no growing cache |
| 3 | Nemotron 3 Super 120B-A12B (MoE) | 123.6B12.0B 激活 | 0.25 GB | 8 of its 88 layers use full attention and 80 are Mamba or feed-forward layers with no growing cache |
| 4 | LFM2.5 8B-A1B (MoE) | 8.5B1.5B 激活 | 0.38 GB | 6 of its 24 layers use full attention and 18 are short-convolution layers with no growing cache |
| 5 | GLM-5.3 Flash | 321.3B18.0B 激活 | 0.39 GB | 11 of its 45 layers use multi-head latent attention and 34 are linear-attention layers with no growing cache |
| 6 | Limite 1B Violetto | 1.0B | 0.44 GB | 12 of its 48 layers use full attention and 36 keep a sliding window of 1,025 tokens |
| 7 | Nemotron 3 Nano 4B | 4.0B | 0.50 GB | 4 of its 42 layers use full attention and 38 are Mamba or feed-forward layers with no growing cache |
| 8 | Muse Glimmer 30B | 29.8B | 0.50 GB | 13 of its 52 layers use full attention and 39 keep a sliding window of 2,048 tokens |
| 9 | Gemma 4 E4B | 8.0B | 0.54 GB | 4 of its 42 layers use full attention, 20 keep a sliding window of 512 tokens and 18 reuse the cache of earlier layers |
| 10 | Ornith 1.0 35B (MoE) | 35.1B3.0B 激活 | 0.63 GB | 10 of its 40 layers use full attention and 30 are linear-attention layers with no growing cache |
| 11 | Ornith 1.5 35B-A3B (MoE) | 36.0B3.0B 激活 | 0.63 GB | 10 of its 40 layers use full attention and 30 are linear-attention layers with no growing cache |
| 12 | Qwen3.6 35B-A3B (MoE) | 36.0B3.0B 激活 | 0.63 GB | 10 of its 40 layers use full attention and 30 are linear-attention layers with no growing cache |
| 13 | AliceAI Foundation 80B-A3B (MoE) | 81.3B3.0B 激活 | 0.75 GB | 12 of its 48 layers use full attention and 36 are KDA recurrent layers with no growing cache |
| 14 | Qwen3-Coder-Next (80B MoE) | 79.7B3.0B 激活 | 0.75 GB | 12 of its 48 layers use full attention and 36 are linear-attention layers with no growing cache |
| 15 | Qwen3.5 122B-A10B (MoE) | 125.1B10.0B 激活 | 0.75 GB | 12 of its 48 layers use full attention and 36 are linear-attention layers with no growing cache |
| 16 | Qwen3.8 Flash Next (180B MoE) | 180.0B6.0B 激活 | 0.75 GB | 12 of its 48 layers use full attention and 36 are linear-attention layers with no growing cache |
| 17 | gpt-oss-20b | 20.9B3.6B 激活 | 0.77 GB | 12 of its 24 layers use full attention and 12 keep a sliding window of 128 tokens |
| 18 | Kimi K3 | 2.78T104.0B 激活 | 0.84 GB | 24 of its 93 layers use multi-head latent attention and 69 are linear-attention layers with no growing cache |
| 19 | MiMo V2.6 Flash | 310.8B15.0B 激活 | 0.85 GB | 9 of its 48 layers use full attention and 39 keep a sliding window of 128 tokens |
| 20 | Gemma 4 26B-A4B (MoE) | 25.8B4.0B 激活 | 0.92 GB | 5 of its 30 layers use full attention and 25 keep a sliding window of 1,024 tokens |
| 21 | Gemma 4 12B | 12.0B | 0.97 GB | 8 of its 48 layers use full attention and 40 keep a sliding window of 1,024 tokens |
| 22 | LensVLM 9B | 9.4B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 23 | MiMo V2.6 Distill Qwen 9B | 9.4B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 24 | Ornith 1.0 9B | 9.4B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 25 | Ornith 1.5 9B | 9.7B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 26 | Qwen3.5 9B | 9.7B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 27 | ZDTaichu 5.0 9B | 9.8B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 28 | gpt-oss-120b | 116.8B5.1B 激活 | 1.15 GB | 18 of its 36 layers use full attention and 18 keep a sliding window of 128 tokens |
| 29 | Spark-X2.5 4B | 4.1B | 1.23 GB | 9 of its 36 layers use full attention and 27 keep a sliding window of 512 tokens |
| 30 | MiniCPM5 2B | 2.5B | 1.31 GB | All 42 layers use full attention |
| 31 | Xing 4.0 29B-A4B (MoE) | 31.2B4.0B 激活 | 1.41 GB | All 40 layers use multi-head latent attention |
| 32 | Step 3.7 Flash 196B-A11B (MoE) | 201.4B11.0B 激活 | 1.63 GB | 12 of its 45 layers use full attention and 33 keep a sliding window of 512 tokens |
| 33 | GLM-4.7 Flash | 31.2B3.0B 激活 | 1.65 GB | All 47 layers use multi-head latent attention |
| 34 | MiMo V2.6 Pro | 1.02T42.0B 激活 | 1.78 GB | 10 of its 70 layers use full attention and 60 keep a sliding window of 128 tokens |
| 35 | Hemmingway-1 27B | 27.3B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 36 | LLM-jp-4.1 32B-A3B Thinking (MoE) | 32.1B3.8B 激活 | 2.00 GB | All 32 layers use full attention |
| 37 | Qwen3.6 27B | 27.8B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 38 | Qwen3.8 27B | 27.8B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 39 | ThinkingCap Qwen3.8 27B | 27.8B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 40 | DeepSeek V3 / R1 (671B) | 684.5B37.0B 激活 | 2.14 GB | All 61 layers use multi-head latent attention |
| 41 | DeepSeek V3.2 | 685.4B37.0B 激活 | 2.38 GB | All 61 layers use multi-head latent attention |
| 42 | DeepSeek V4.1 Flash | 763.2B16.0B 激活 | 2.50 GB | All 40 layers use full attention |
| 43 | Granite 4.2 3B | 3.7B | 2.50 GB | All 40 layers use full attention |
| 44 | DeepSeek V4 Flash | 290.9B13.0B 激活 | 2.69 GB | All 43 layers use full attention |
| 45 | DeepSeek V4 Flash 0731 | 304.2B13.0B 激活 | 2.69 GB | All 43 layers use full attention |
| 46 | GLM-5.2 | 753.3B40.0B 激活 | 2.82 GB | All 78 layers use multi-head latent attention |
| 47 | GLM-5.3 | 753.3B40.0B 激活 | 2.82 GB | All 78 layers use multi-head latent attention |
| 48 | Hy4 Preview 770B-A49B (MoE) | 780.0B49.0B 激活 | 2.82 GB | All 78 layers use multi-head latent attention |
| 49 | Qwen3.8 2.4T-A95B (MoE) | 2.45T95.0B 激活 | 2.88 GB | 23 of its 92 layers use full attention and 69 are linear-attention layers with no growing cache |
| 50 | Qwen3 30B-A3B (MoE) | 30.5B3.3B 激活 | 3.00 GB | All 48 layers use full attention |
| 51 | Qwen3-Coder 30B-A3B (MoE) | 30.5B3.3B 激活 | 3.00 GB | All 48 layers use full attention |
| 52 | Gemma 4 31B | 31.3B | 3.67 GB | 10 of its 60 layers use full attention and 50 keep a sliding window of 1,024 tokens |
| 53 | MiniMax M3 | 427.0B23.0B 激活 | 3.75 GB | All 60 layers use full attention |
| 54 | DeepSeek V4 Pro | 1.60T49.0B 激活 | 3.81 GB | All 61 layers use full attention |
| 55 | Llama 3.1 8B | 8.0B | 4.00 GB | All 32 layers use full attention |
| 56 | IQuest-Q1 320B-A15B (MoE) | 320.3B15.0B 激活 | 4.23 GB | 25 of its 88 layers use full attention and 63 keep a sliding window of 4,096 tokens |
| 57 | Qwen3 8B | 8.2B | 4.50 GB | All 36 layers use full attention |
| 58 | Granite 4.2 8B | 8.8B | 5.00 GB | All 40 layers use full attention |
| 59 | K2-Horizon MoVA 36B-A4B (MoE) | 37.4B4.0B 激活 | 6.00 GB | All 48 layers use full attention |
| 60 | MiniMax M2.7 | 228.7B10.0B 激活 | 7.75 GB | All 62 layers use full attention |
| 61 | Granite 4.2 30B | 29.3B | 8.00 GB | All 64 layers use full attention |
| 62 | Llama 3.1 70B | 70.6B | 10.00 GB | All 80 layers use full attention |
| 63 | Mistral Medium 3.5 128B | 127.7B | 11.00 GB | All 88 layers use full attention |
下载与嵌入
- gpu-tiers.csv (上面的显存分档表)
- kv-cache-32k.csv (63 个模型的 KV 缓存排行)
- kv-cache-32k.svg (KV 缓存图表,可直接转载)
- 逐模型的完整数据:modelvram-vram.csv, modelvram-vram.json,
/api/v1/models.json
把图表放进你的文章,复制这段代码(图片链接回本报告,并附署名):
<a href="https://modelvram.com/reports/local-llm-vram-2026/"><img src="https://modelvram.com/reports/local-llm-vram-2026/kv-cache-32k.svg" width="760" height="1226" alt="KV cache at 32K context for 63 open LLMs, from 0.19 GB to 11.0 GB" loading="lazy"></a>
<p>Source: <a href="https://modelvram.com/reports/local-llm-vram-2026/">ModelVRAM 2026 Local LLM VRAM Report</a> (CC BY 4.0)</p> 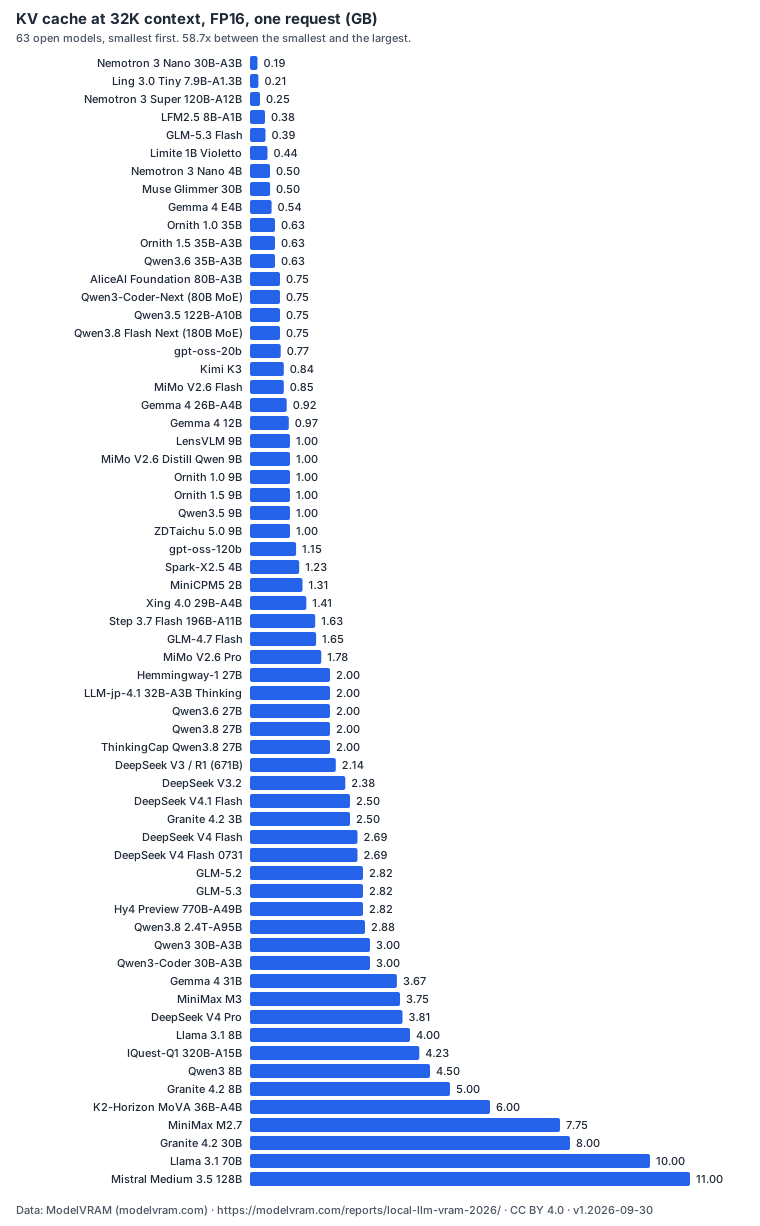
方法与局限
模型的层数、注意力结构和参数量读取自 Hugging Face 上各仓库的 config.json 与文件大小。总显存 = 权重 + FP16 KV 缓存 + 0.5 GB + 权重与缓存的 10%。KV 缓存按实际结构计算:全注意力层随上下文增长,滑动窗口层只保留窗口,MLA 保存压缩的潜向量,线性注意力和状态空间层不随上下文增长。
局限:只算单个请求;不含 vLLM 的 gpu_memory_utilization 预留、CUDA Graph 和视觉编码器;这些是估算值,不是实测峰值。与 20 条公开 llama.cpp / vLLM 实测的对比见估算准确度。任意其他设置可以在显存计算器里重算。
更新:本页与开放数据集同步,数据变化时随站点重新生成;引用时请注明上面的数据版本号,以便对应到具体数字。首次发布于 。