2026 Local LLM VRAM Report: 64 Open Models on 8–80 GB GPUs and Macs
Every number in this report is computed at build time from the site's 64 open models with the same functions as the VRAM calculator; none is typed in. Setting: Q4_K_M weights (gpt-oss at its published MXFP4), 32K context, one request, FP16 KV cache, and a model fits only with 0.5 GB left free. Data version 1.2026-09-30, model data checked . GB means GiB.
Key findings you can quote
- At 32K context, the FP16 KV cache of one request ranges from 0.19 GB (Nemotron 3 Nano 30B-A3B) to 11.0 GB (Mistral Medium 3.5 128B) across 63 open models, a 58.7-fold difference.
- Parameter count does not predict the cache: Nemotron 3 Nano 30B-A3B (31.6B parameters) needs 0.19 GB of KV cache at 32K, while Granite 4.2 30B (29.3B) needs 8.0 GB, 43 times more.
- 34 of 64 open models fit a 24 GB GPU at Q4_K_M with 32K context; the largest is Ornith 1.5 35B-A3B at 23.5 GB.
- A 48 GB GPU holds no larger model than a 32 GB one at Q4_K_M with 32K: both top out at K2-Horizon MoVA 36B-A4B, which gains context (37K to 115K tokens) rather than parameters; Llama 3.1 70B needs 55.2 GB.
- A 128 GB Mac, with 96 GB usable by the GPU, runs 44 of the 64 models at Q4_K_M with 32K, up to Mistral Medium 3.5 128B (127.7B, 91.8 GB).
How to cite
Plain text: Data: ModelVRAM (modelvram.com), "2026 Local LLM VRAM Report", https://modelvram.com/reports/local-llm-vram-2026/, data version 1.2026-09-30 (2026-09-30), CC BY 4.0.
APA: ModelVRAM. (2026). 2026 Local LLM VRAM Report (Version 1.2026-09-30) [Data set]. https://modelvram.com/reports/local-llm-vram-2026/
The data is under CC BY 4.0: copy, adapt and use it commercially, crediting "Data: ModelVRAM" with a link to this page.
The largest model each memory size holds (Q4_K_M, 32K)
Largest by total parameters; "longest context" is how far that model's context goes on the tier with 0.5 GB still free. Macs count the unified memory macOS lets the GPU use.
| Memory | Models that fit | Largest model | Setting | VRAM at 32K | Longest context |
|---|---|---|---|---|---|
| 8 GB GPU | 11 / 64 | LensVLM 9B | Q4_K_M | 7.43 GB | 33K |
| 12 GB GPU | 18 / 64 | Gemma 4 12B | Q4_K_M | 8.98 GB | 178K |
| 16 GB GPU | 19 / 64 | gpt-oss-20b | MXFP4 | 15.44 GB | 34K |
| 24 GB GPU | 34 / 64 | Ornith 1.5 35B-A3B (MoE) | Q4_K_M | 23.47 GB | 33K |
| 32 GB GPU | 37 / 64 | K2-Horizon MoVA 36B-A4B (MoE) | Q4_K_M | 30.31 GB | 37K |
| 48 GB GPU | 37 / 64 | K2-Horizon MoVA 36B-A4B (MoE)same as the smaller tier | Q4_K_M | 30.31 GB | 115K |
| 80 GB GPU | 43 / 64 | Qwen3.5 122B-A10B (MoE) | Q4_K_M | 78.85 GB | 57K |
| 64 GB Mac (48 GB usable) | 37 / 64 | K2-Horizon MoVA 36B-A4B (MoE)same as the smaller tier | Q4_K_M | 30.31 GB | 115K |
| 128 GB Mac (96 GB usable) | 44 / 64 | Mistral Medium 3.5 128B | Q4_K_M | 91.75 GB | 41K |
The 48 GB gap
A 48 GB card (and a 64 GB Mac) holds no larger model than a 32 GB card: both top out at K2-Horizon MoVA 36B-A4B (MoE), and the extra memory only takes its context from 37K to 115K tokens. The dataset has 1 model between 40B and 75B parameters (Llama 3.1 70B, 55.2 GB at Q4_K_M with 32K), and none fits 48 GB. This is a gap in the dataset's coverage, not proof that no model of that size runs on 48 GB; no figures have been made up to fill it.
KV cache at 32K context, smallest to largest
One request, FP16. The smallest, Nemotron 3 Nano 30B-A3B (MoE), needs 0.19 GB; the largest, Mistral Medium 3.5 128B, 11.0 GB: 58.7 times more. The attention layout decides it: hybrid models that keep full keys and values in only a few layers cache far less than models with full attention in every layer.
| # | Model | Parameters | KV cache at 32K | Attention layout |
|---|---|---|---|---|
| 1 | Nemotron 3 Nano 30B-A3B (MoE) | 31.6B3.5B active | 0.19 GB | 6 of its 52 layers use full attention and 46 are Mamba or feed-forward layers with no growing cache |
| 2 | Ling 3.0 Tiny 7.9B-A1.3B (MoE) | 7.9B1.3B active | 0.21 GB | 6 of its 24 layers use multi-head latent attention and 18 are KDA recurrent layers with no growing cache |
| 3 | Nemotron 3 Super 120B-A12B (MoE) | 123.6B12.0B active | 0.25 GB | 8 of its 88 layers use full attention and 80 are Mamba or feed-forward layers with no growing cache |
| 4 | LFM2.5 8B-A1B (MoE) | 8.5B1.5B active | 0.38 GB | 6 of its 24 layers use full attention and 18 are short-convolution layers with no growing cache |
| 5 | GLM-5.3 Flash | 321.3B18.0B active | 0.39 GB | 11 of its 45 layers use multi-head latent attention and 34 are linear-attention layers with no growing cache |
| 6 | Limite 1B Violetto | 1.0B | 0.44 GB | 12 of its 48 layers use full attention and 36 keep a sliding window of 1,025 tokens |
| 7 | Nemotron 3 Nano 4B | 4.0B | 0.50 GB | 4 of its 42 layers use full attention and 38 are Mamba or feed-forward layers with no growing cache |
| 8 | Muse Glimmer 30B | 29.8B | 0.50 GB | 13 of its 52 layers use full attention and 39 keep a sliding window of 2,048 tokens |
| 9 | Gemma 4 E4B | 8.0B | 0.54 GB | 4 of its 42 layers use full attention, 20 keep a sliding window of 512 tokens and 18 reuse the cache of earlier layers |
| 10 | Ornith 1.0 35B (MoE) | 35.1B3.0B active | 0.63 GB | 10 of its 40 layers use full attention and 30 are linear-attention layers with no growing cache |
| 11 | Ornith 1.5 35B-A3B (MoE) | 36.0B3.0B active | 0.63 GB | 10 of its 40 layers use full attention and 30 are linear-attention layers with no growing cache |
| 12 | Qwen3.6 35B-A3B (MoE) | 36.0B3.0B active | 0.63 GB | 10 of its 40 layers use full attention and 30 are linear-attention layers with no growing cache |
| 13 | AliceAI Foundation 80B-A3B (MoE) | 81.3B3.0B active | 0.75 GB | 12 of its 48 layers use full attention and 36 are KDA recurrent layers with no growing cache |
| 14 | Qwen3-Coder-Next (80B MoE) | 79.7B3.0B active | 0.75 GB | 12 of its 48 layers use full attention and 36 are linear-attention layers with no growing cache |
| 15 | Qwen3.5 122B-A10B (MoE) | 125.1B10.0B active | 0.75 GB | 12 of its 48 layers use full attention and 36 are linear-attention layers with no growing cache |
| 16 | Qwen3.8 Flash Next (180B MoE) | 180.0B6.0B active | 0.75 GB | 12 of its 48 layers use full attention and 36 are linear-attention layers with no growing cache |
| 17 | gpt-oss-20b | 20.9B3.6B active | 0.77 GB | 12 of its 24 layers use full attention and 12 keep a sliding window of 128 tokens |
| 18 | Kimi K3 | 2.78T104.0B active | 0.84 GB | 24 of its 93 layers use multi-head latent attention and 69 are linear-attention layers with no growing cache |
| 19 | MiMo V2.6 Flash | 310.8B15.0B active | 0.85 GB | 9 of its 48 layers use full attention and 39 keep a sliding window of 128 tokens |
| 20 | Gemma 4 26B-A4B (MoE) | 25.8B4.0B active | 0.92 GB | 5 of its 30 layers use full attention and 25 keep a sliding window of 1,024 tokens |
| 21 | Gemma 4 12B | 12.0B | 0.97 GB | 8 of its 48 layers use full attention and 40 keep a sliding window of 1,024 tokens |
| 22 | LensVLM 9B | 9.4B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 23 | MiMo V2.6 Distill Qwen 9B | 9.4B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 24 | Ornith 1.0 9B | 9.4B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 25 | Ornith 1.5 9B | 9.7B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 26 | Qwen3.5 9B | 9.7B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 27 | ZDTaichu 5.0 9B | 9.8B | 1.00 GB | 8 of its 32 layers use full attention and 24 are linear-attention layers with no growing cache |
| 28 | gpt-oss-120b | 116.8B5.1B active | 1.15 GB | 18 of its 36 layers use full attention and 18 keep a sliding window of 128 tokens |
| 29 | Spark-X2.5 4B | 4.1B | 1.23 GB | 9 of its 36 layers use full attention and 27 keep a sliding window of 512 tokens |
| 30 | MiniCPM5 2B | 2.5B | 1.31 GB | All 42 layers use full attention |
| 31 | Xing 4.0 29B-A4B (MoE) | 31.2B4.0B active | 1.41 GB | All 40 layers use multi-head latent attention |
| 32 | Step 3.7 Flash 196B-A11B (MoE) | 201.4B11.0B active | 1.63 GB | 12 of its 45 layers use full attention and 33 keep a sliding window of 512 tokens |
| 33 | GLM-4.7 Flash | 31.2B3.0B active | 1.65 GB | All 47 layers use multi-head latent attention |
| 34 | MiMo V2.6 Pro | 1.02T42.0B active | 1.78 GB | 10 of its 70 layers use full attention and 60 keep a sliding window of 128 tokens |
| 35 | Hemmingway-1 27B | 27.3B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 36 | LLM-jp-4.1 32B-A3B Thinking (MoE) | 32.1B3.8B active | 2.00 GB | All 32 layers use full attention |
| 37 | Qwen3.6 27B | 27.8B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 38 | Qwen3.8 27B | 27.8B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 39 | ThinkingCap Qwen3.8 27B | 27.8B | 2.00 GB | 16 of its 64 layers use full attention and 48 are linear-attention layers with no growing cache |
| 40 | DeepSeek V3 / R1 (671B) | 684.5B37.0B active | 2.14 GB | All 61 layers use multi-head latent attention |
| 41 | DeepSeek V3.2 | 685.4B37.0B active | 2.38 GB | All 61 layers use multi-head latent attention |
| 42 | DeepSeek V4.1 Flash | 763.2B16.0B active | 2.50 GB | All 40 layers use full attention |
| 43 | Granite 4.2 3B | 3.7B | 2.50 GB | All 40 layers use full attention |
| 44 | DeepSeek V4 Flash | 290.9B13.0B active | 2.69 GB | All 43 layers use full attention |
| 45 | DeepSeek V4 Flash 0731 | 304.2B13.0B active | 2.69 GB | All 43 layers use full attention |
| 46 | GLM-5.2 | 753.3B40.0B active | 2.82 GB | All 78 layers use multi-head latent attention |
| 47 | GLM-5.3 | 753.3B40.0B active | 2.82 GB | All 78 layers use multi-head latent attention |
| 48 | Hy4 Preview 770B-A49B (MoE) | 780.0B49.0B active | 2.82 GB | All 78 layers use multi-head latent attention |
| 49 | Qwen3.8 2.4T-A95B (MoE) | 2.45T95.0B active | 2.88 GB | 23 of its 92 layers use full attention and 69 are linear-attention layers with no growing cache |
| 50 | Qwen3 30B-A3B (MoE) | 30.5B3.3B active | 3.00 GB | All 48 layers use full attention |
| 51 | Qwen3-Coder 30B-A3B (MoE) | 30.5B3.3B active | 3.00 GB | All 48 layers use full attention |
| 52 | Gemma 4 31B | 31.3B | 3.67 GB | 10 of its 60 layers use full attention and 50 keep a sliding window of 1,024 tokens |
| 53 | MiniMax M3 | 427.0B23.0B active | 3.75 GB | All 60 layers use full attention |
| 54 | DeepSeek V4 Pro | 1.60T49.0B active | 3.81 GB | All 61 layers use full attention |
| 55 | Llama 3.1 8B | 8.0B | 4.00 GB | All 32 layers use full attention |
| 56 | IQuest-Q1 320B-A15B (MoE) | 320.3B15.0B active | 4.23 GB | 25 of its 88 layers use full attention and 63 keep a sliding window of 4,096 tokens |
| 57 | Qwen3 8B | 8.2B | 4.50 GB | All 36 layers use full attention |
| 58 | Granite 4.2 8B | 8.8B | 5.00 GB | All 40 layers use full attention |
| 59 | K2-Horizon MoVA 36B-A4B (MoE) | 37.4B4.0B active | 6.00 GB | All 48 layers use full attention |
| 60 | MiniMax M2.7 | 228.7B10.0B active | 7.75 GB | All 62 layers use full attention |
| 61 | Granite 4.2 30B | 29.3B | 8.00 GB | All 64 layers use full attention |
| 62 | Llama 3.1 70B | 70.6B | 10.00 GB | All 80 layers use full attention |
| 63 | Mistral Medium 3.5 128B | 127.7B | 11.00 GB | All 88 layers use full attention |
Download and embed
- gpu-tiers.csv (the memory tier table above)
- kv-cache-32k.csv (the KV cache ranking of 63 models)
- kv-cache-32k.svg (the KV cache chart, free to republish)
- Full per-model data: modelvram-vram.csv, modelvram-vram.json,
/api/v1/models.json
To put the chart in your article, copy this code (the image links back to this report, with its credit):
<a href="https://modelvram.com/reports/local-llm-vram-2026/"><img src="https://modelvram.com/reports/local-llm-vram-2026/kv-cache-32k.svg" width="760" height="1226" alt="KV cache at 32K context for 63 open LLMs, from 0.19 GB to 11.0 GB" loading="lazy"></a>
<p>Source: <a href="https://modelvram.com/reports/local-llm-vram-2026/">ModelVRAM 2026 Local LLM VRAM Report</a> (CC BY 4.0)</p> 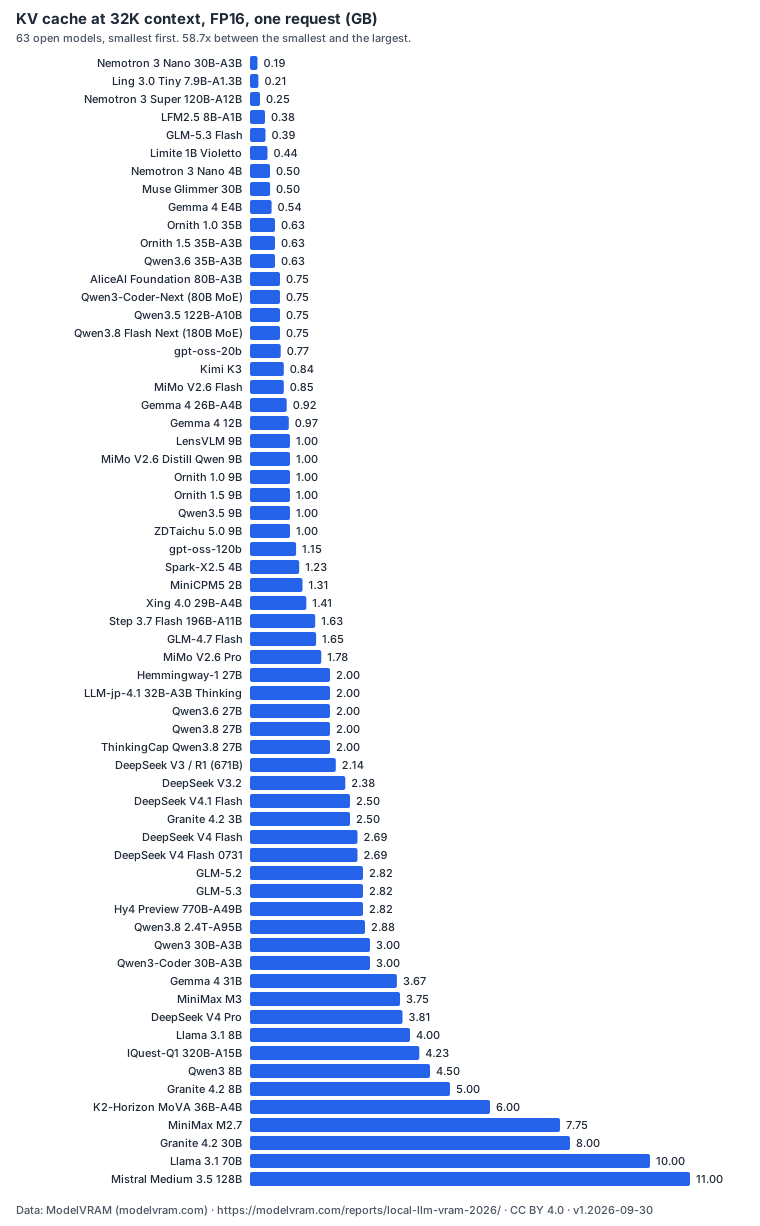
Method and limits
Each model's layers, attention layout and parameter count are read from its repository's config.json and file sizes on Hugging Face. Total = weights + FP16 KV cache + 0.5 GB + 10% of weights and cache. The KV cache follows the real layout: full-attention layers grow with context, sliding-window layers keep only their window, MLA stores a compressed latent, and linear-attention or state-space layers do not grow.
Limits: one request only; vLLM's gpu_memory_utilization reservation, CUDA graphs and vision encoders are left out; these are estimates, not measured peaks. See predicted vs measured for how they compare with 20 public llama.cpp and vLLM measurements, and the LLM VRAM Calculator for any other setting.
Updates: this page is generated with the open dataset and changes when the data does; cite the data version above so a reader can match your numbers. First published .