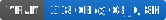
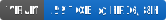
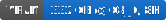
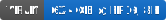
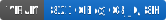
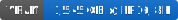
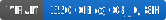
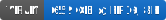
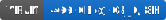
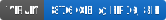
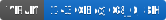
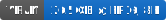
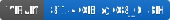
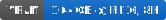
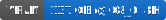
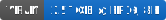
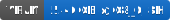
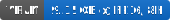
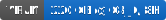
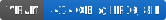
VRAM badges for model cards
A small badge for a model's README that shows how much GPU memory it needs and links to the model's page here. Each one is a static SVG file, rebuilt with the site from the same estimate as the model page.
How to use it
Paste the Markdown into the README of a Hugging Face or GitHub repository, for example a GGUF upload:
[](https://modelvram.com/llm-vram-calculator/qwen3.6-35b-a3b/)Or, where Markdown is not available, the HTML:
<a href="https://modelvram.com/llm-vram-calculator/qwen3.6-35b-a3b/"><img src="https://modelvram.com/badge/qwen3.6-35b-a3b.svg" alt="Qwen3.6 35B-A3B VRAM: 23.0 GB at Q4_K_M, 8K context"></a>
Replace qwen3.6-35b-a3b with the last part of the model page's address (the table below links every one); the model page
and the calculator show the code ready to copy. The address is
https://modelvram.com/badge/<model>.svg for Q4_K_M, with -q8 or -fp16 before
.svg for Q8_0 and FP16.
What the number means
The total GPU memory for one request with 8,192 tokens of context and an FP16 KV cache: the weights at that precision, the cache for the model's attention layout, and 0.5 GB plus 10% for the runtime. GB means GiB. It is an estimate, not a measured peak; the model page breaks it down and the calculator changes the context, the number of requests and the cache precision.
Models with a badge
55 models, each at Q4_K_M, Q8_0 and FP16. The model name opens its page. For gpt-oss-20b and gpt-oss-120b, the Q8_0 badge shows MXFP4 as published: their GGUF quants keep the experts in MXFP4, so a Q8_0 file is about that size.